
v1.5.0 — Menu bar, new dashboard, 10x lighter DeepSeek cache, trustworthy pack updates
-
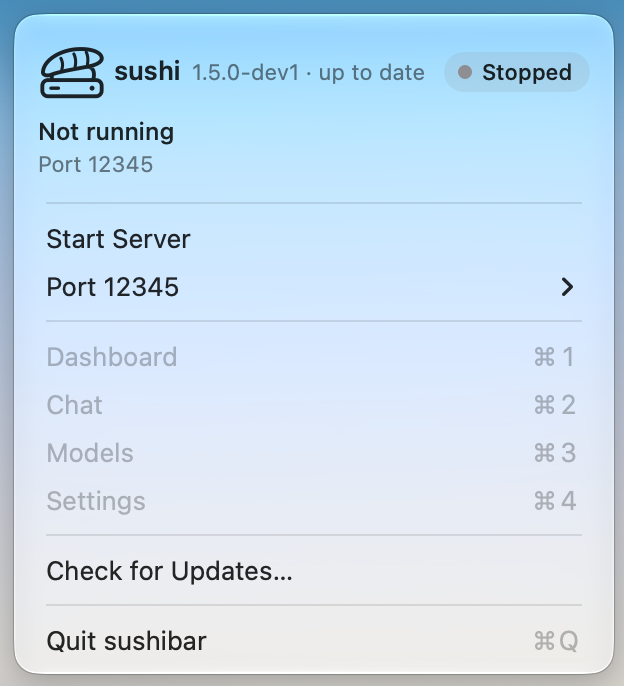
sushibarputs sushi in the menu bar: a native app besidesushishows live decode speed and a status card
(model, memory, prefill, GPU clock, a five-minute decode graph), starts and stops the server on any port, opens the
dashboard and chat, and installs sushi updates.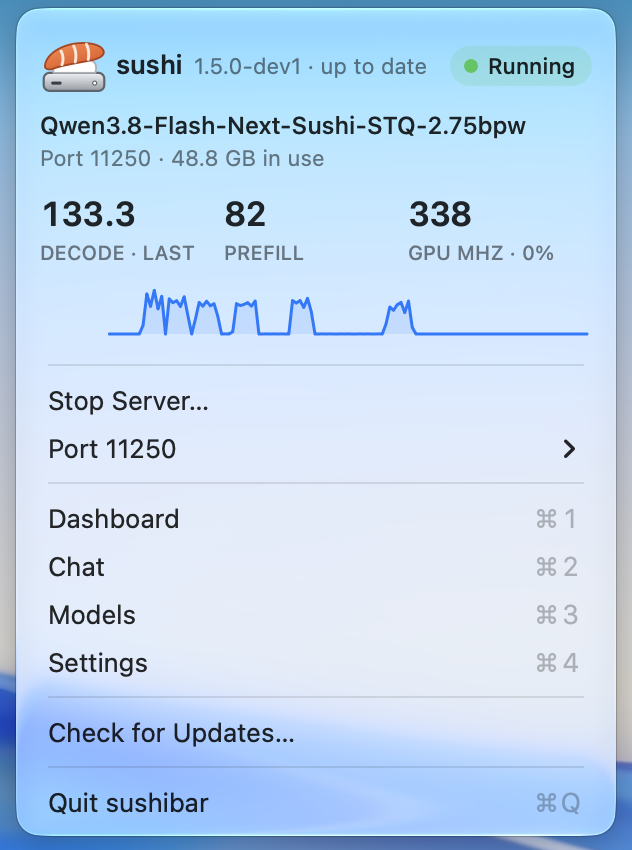
-
DeepSeek-V4.1's SSD prefix cache writes about 10x less: each context row reaches the SSD once per conversation
instead of once per turn, so a turn's write no longer grows with the context. Over a week of long agent sessions 1.4
wrote 120 GB to the cache, about 100 MB a turn; 1.5.0 writes about 9 MB a turn, and a 30-turn session from 72k to 176k
tokens wrote 0.8 GB instead of 3.8 GB with the same restore after a restart. Caches from earlier versions are not
read; clear them in Settings. -
A new web page that opens on the Dashboard: Dashboard, Chat, Models and Settings tabs (Cmd+1 to Cmd+4); a Compact
view with one point per finished request and the GPU clock beside utilization; Models and Settings edit each model's
settings and the SSD prefix cache, offering only what that model honours and naming the volume the cache writes to
with its free space (thanks @cyrilmhansen). The page answers while a model is still loading, and metrics are on by
default. -
Pack updates you can trust:
sushi pullcompares file contents instead of sizes and verifies every download, a
pack folder that mixes two uploads is refused at load naming the file, andsushi list, the Models tab andsushibar
say when a newer revision of your pack is published. -
DeepSeek-V4.1 pair-major packs: a new expert layout the streaming engine reads straight into its pools;
sushi repack <pack>converts a downloaded pack in place, orsushi pullfetches the new revision once it is published.
Versions before 1.5.0 refuse a pair-major pack by name. -
Faster, steadier DeepSeek-V4.1 decode: DSpark verifies up to seven copied tokens a round when a reply echoes its
context (ported from CommunityServe/plugins, thanks @STRML), greedy text no longer varies between runs, decode spends
less CPU per token, streamed experts fill faster with identical output, and--ssd-prefetch Nmakes expert prefetch
opt-in under an SSD read cap. -
Smaller fixes: DeepSeek-V4.1 raw-text
/v1/completionsno longer stops at the first token,sushi benchno
longer needs sudo, redirected output appends instead of overwriting,sushi update --checknames a network failure,
and the Models list hides test fixtures and no longer counts linked Engram shards as the pack's size.