v1.4.0 — DeepSeek-V4.1-Flash, Qwen STQ 2.75bpw, sushi bench
- DeepSeek-V4.1-Flash on a 128 GB Mac: the new DeepSeek-V4.1-Flash-1017-Sushi-STQ-1.75bpw pack (332 GB with its Engram tables) streams its routed experts from the SSD within
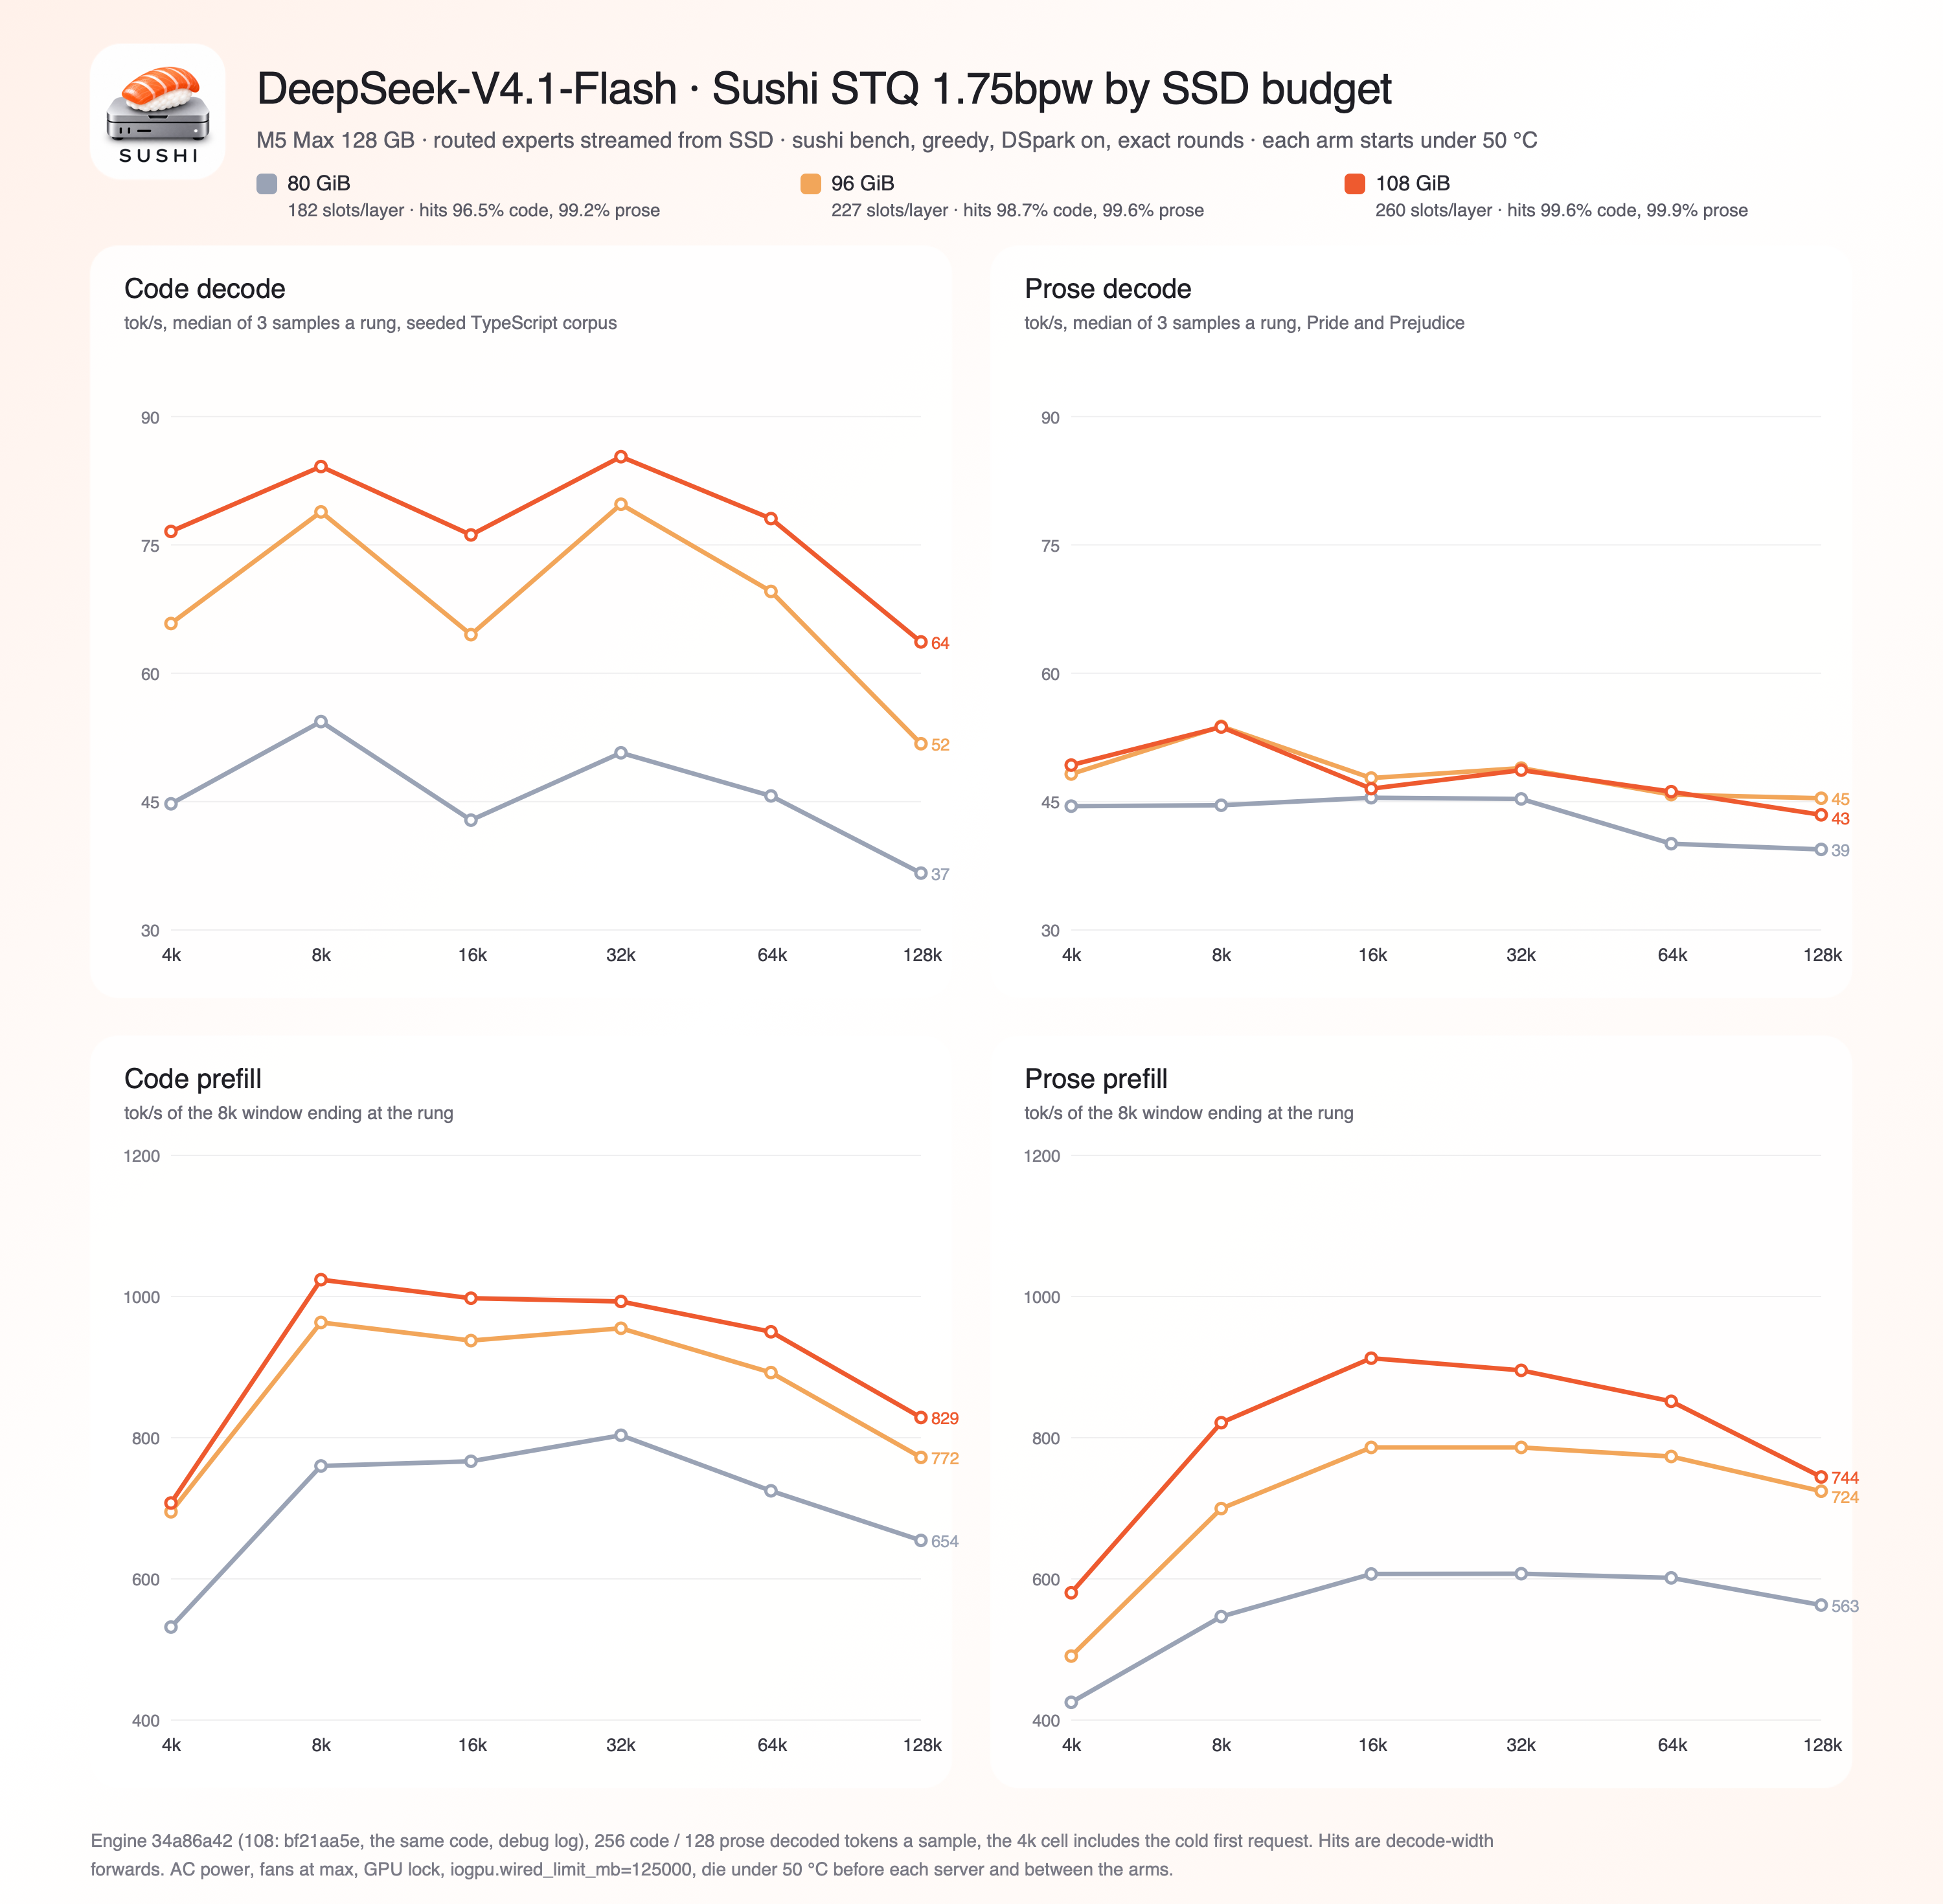
--ssd-budget-gb, with DSpark speculative decoding, image input on by default, up to 1M tokens of context, DSML tool calls, thinking at high effort by default and--drop-expertto trade a few re-routed experts for memory. Greedy DSpark output is the same from run to run on the same Mac (SUSHI_DSV41_DSPARK_EXACT=0trades that for a plain step about 0.3 ms faster). On an M5 Max it decodes 76.6 tok/s at 4k on code and 49.3 on prose, and prefills 1,024 tok/s (sushi bench,--ssd-budget-gb 108). - Long agent sessions on DeepSeek resume where they left off: the SSD prefix cache keeps a restore point every 8192 tokens, a follow-up turn that diverges inside the last answer rolls the live state back in place with no SSD read, a thinking turn restores from its own thought, and a request may carry up to 1024 images, of which only those the restored prefix does not hold are decoded and encoded again.
- Qwen3.8-Flash-Next Sushi-STQ-2.75bpw replaces Sushi-2.6bpw and Sushi-3bpw as the 64 GB recommendation (
sushi pull qwen3.8-flash-next, KLD 0.0692 at 16x512). Qwen now thinks at medium effort by default, runs Claude-style<function_calls>markup as tool calls, and skips the MTP head's 1.2 GB at load under--no-mtp.sushi pullandsushi listuse the tokenhf auth loginsaved, so a private pack you have access to lists with its size and pulls withoutHF_TOKEN. Thanks to @bobosola for the report (#63). - Faster speculative decoding: Qwen verifies 2 to 8 rows at an even price per row (an eight-row verify about 16% faster), DFlash2 now serves Qwen's image, video and sampled requests (about 1.7-2x plain decoding), GLM-5.3-Flash gets adaptive DFlash2 over 2 to 8 rows, and Macs without matrix units verify 3 to 8 rows up to 2x faster, all with output byte-identical to before.
- Memory you can trust: admission plans under the GPU memory other apps hold and counts MLX's command buffers, a Metal out-of-memory failure no longer fails the request after it, DFlash2 reserves exactly what it uses (about 2.8 GB more fits at 1M context), and DeepSeek keeps MLX's buffer pool inside its budget. Thanks to @holistech for the report (#61).
sushi benchdrives a running server through the release bench: one cold prefill in 8k restore windows up to 128k and three decode samples a rung, on a code and a prose corpus, with the GPU clock read beside every request.frequency_penaltynow follows OpenAI's definition.sushi convert exl3 --codebookis now--expert-codebook(breaking):--codebook mcgbecomes--expert-codebook exl3-mcgand--codebook mul1becomes--expert-codebook exl3-mul1; packs and resumable runs are unchanged.