
Huge open models on the machine you already have: on the CPU, on any GPU through Vulkan, on NVIDIA cards through CUDA. Pure C, one file per model family.
387 pull requests since v2.0.0, 208 of them from 35 contributors. GGUF files now run natively on every engine, read exactly as published. Four new models arrive, Mistral-Large-4 (1T) among them. CUDA gets device chains of its own and a routed-expert tier for every engine. Qwen3.8-Flash-Next runs a 256k context at the speed of 64k, an agent's turns read only what is new, and there is a new chat UI.
Highlights
- GGUF on every engine.
coli importtakes a GGUF where it lies and every engine runs it as published: no conversion, no second quantization, from IQ1_S to Q8_0, F16, BF16 and MXFP4, the same blocks and the same tokens on the CPU, Vulkan and CUDA. unsloth's Dynamic UD quants run as they are (docs/gguf.md). - New models. Mistral-Large-4 (1T, 52B active: text, pictures, reasoning, tools), Muse Spark Open (816B), Flint (40B, 2.5B active), LFM3-VL-2B with its vision tower, and the published DeepSeek V4.1 Flash and Kimi K3 GGUFs.
- CUDA. Every layer of Qwen3.6, Qwen3.8 and OLMoE as one chain on the card, a routed-expert tier on the card for every engine, the dense matrices on the card for DeepSeek V4, V4.1, Kimi K3, GLM-5.3 and MiMo, and a GGUF's blocks on CUDA with the prompt on the tensor cores.
- Vulkan. A model larger than the card keeps the experts the card cannot hold in a host pool in RAM, and the CPU computes them inside the device's frame while the card computes its own. Prompts on the matrix units, flash attention with windows and sinks, float16 KV mirrors.
- Long contexts and agents. Qwen3.8-Flash-Next at 262,144 tokens: decode 9.6 to 45.7 tok/s, prompt 15.6 to 149. A short request between two turns (a title, a summary) parks the conversation instead of taking its state, on every engine: a Hermes Agent turn went from 86 s to 4.9 s.
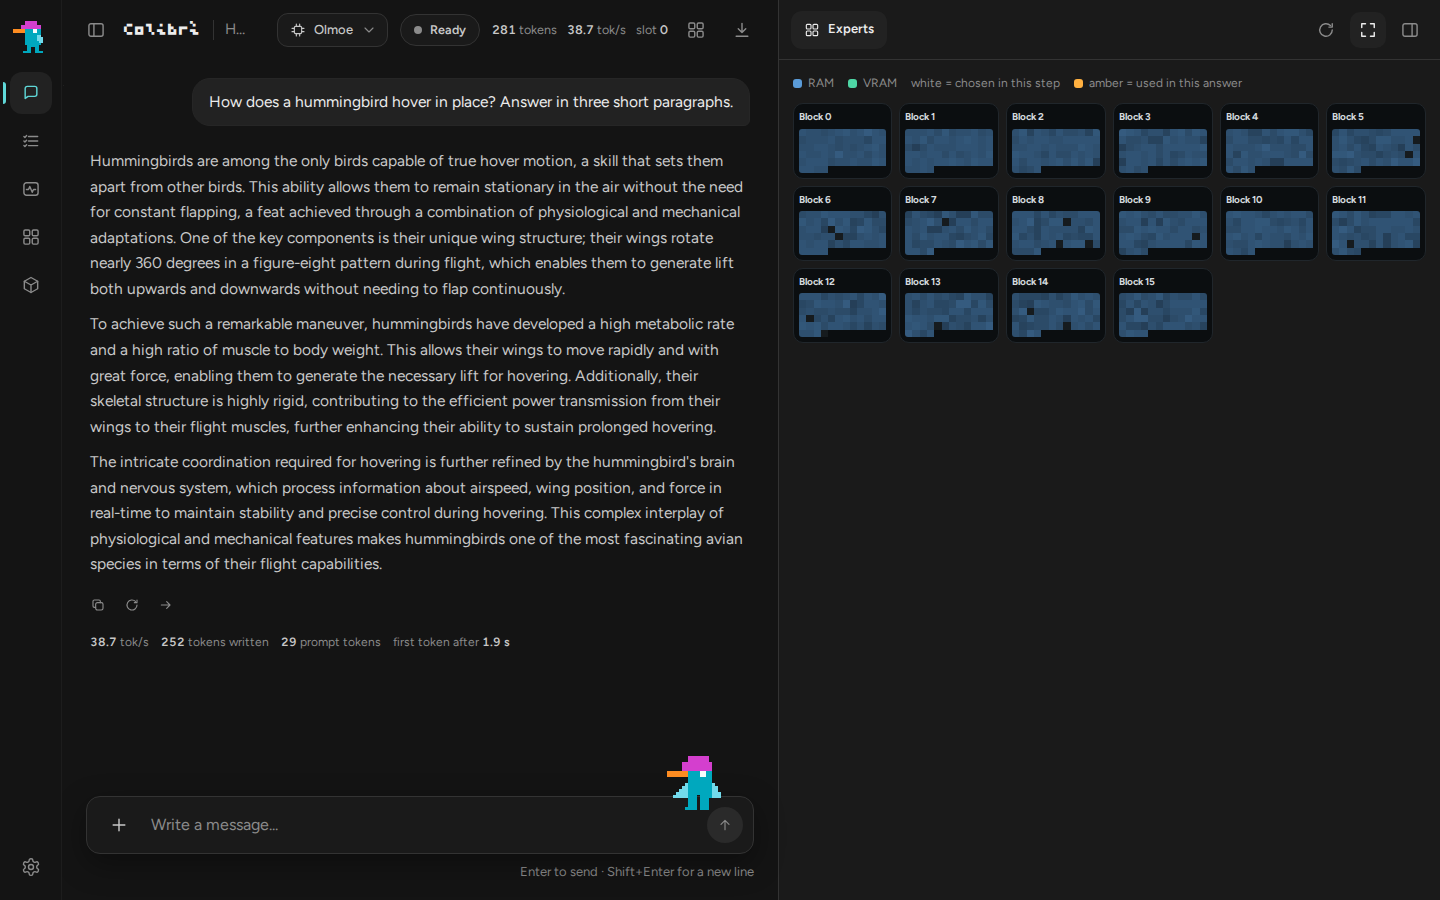
- A new chat UI.
coli ui: reasoning in its own block, pictures, web search, a live map of the experts as they fire, a monitor, your models, and coding agents already pointed at colibri. Seven languages. - Speculative decoding. Qwen3.6's MTP head on every backend (
Q36_MTP=1): decode 99.7-104.5 to 115.8-120.1 tok/s on CUDA, 83.2-83.8 to 99.9-109.3 on Vulkan; DeepSeek V4.1's DSpark head drafts as deep as its confidence says, behind a gate that skips the drafts that cannot pay. - Memory. KV caches in float16: GLM-5.3 at 131,072 tokens in 11.9 GB instead of 23.9.
Measured on one 24 GB card
An i5-13500 with 62 GB of RAM and an RTX PRO 4000 Blackwell SFF (24 GB, 70 W), each model served by coli serve: a fresh 450-token prompt, then a 128-token streamed answer, the request's HTTP included; the better of two runs, tok/s.
| GGUF | CUDA prompt | CUDA decode | Vulkan prompt | Vulkan decode | CPU prompt | CPU decode |
|---|---|---|---|---|---|---|
| Qwen3.6-35B-A3B UD-Q4_K_M | 3,491 | 104.8 | 2,076 | 92.9 | 122.6 | 13.9 |
| LFM3-VL-2B Q4_K_M | 12,317 | 235.1 | 8,174 | 214.1 | 286.5 | 34.5 |
| OLMoE-1B-7B-0125-Instruct Q4_K_M | 10,418 | 354.6 | 6,867 | 299.4 | 279.9 | 47.4 |
| LFM3-VL-2B F16 | 11,524 | 103.4 | 7,767 | 99.3 | 49.7 | 6.4 |
| Qwen3.8-Flash-Next IQ2_XS (68 GB: the experts the card cannot hold stay in RAM) | 217.1 | 51.4 | 214.3 | 50.6 | 38.3 | 9.3 |
Bigger than the RAM, on the same machine
Each model from its published GGUF; what neither the card nor the RAM holds comes from two NVMe drives. Tokens per second, from each model's page in docs/.
| GGUF | size | backend | prompt | decode |
|---|---|---|---|---|
| Inkling-Small UD-IQ2_XXS | 77 GB | Vulkan | 15.1-33.1 | 10.92-11.53 |
| MiMo-V2.6-Flash Q2_K_S | 106 GB | Vulkan | 8.2 | 7.8 |
| DeepSeek V4 Flash 0731 UD-IQ2_XXS | 85 GB | Vulkan | 19.7-20.4 | 6.18-6.25 |
| DeepSeek V4.1 Flash UD-IQ1_S | 233 GB | Vulkan | 31.8 over 3,403 tokens | 5.01-5.29 |
| GLM-5.3-Flash UD-IQ2_XXS | 95 GB | Vulkan | 9.3 | 2.92-3.40 |
| Muse Spark Open UD-IQ1_S | 176 GB | Vulkan | 5.0-5.3 | 1.55-1.58 |
| Mistral-Large-4 UD-IQ1_S | 233 GB | CUDA | 240 tokens in 66-82 s | 1.34-1.36 |
| GLM-5.2 UD-IQ1_S | 202 GB | Vulkan | 0.633-0.658 | |
| Kimi K3 UD-IQ1_S | 594 GB | Vulkan | 31 tokens in 46.5 s | 0.349 |
Run a GGUF
coli import model.gguf                    # the first part of a split file, its other parts next to it
coli chat --model model.colibri           # or coli serve, then coli ui
unsloth's DeepSeek V4.1 Flash, for example:
hf download unsloth/DeepSeek-V4.1-Flash-1017-GGUF --include "UD-IQ1_S/*" --local-dir v41
cd v41/UD-IQ1_S
coli import DeepSeek-V4.1-Flash-1017-UD-IQ1_S-00001-of-00005.gguf
COLI_VULKAN=1 coli chat --model DeepSeek-V4.1-Flash-1017-UD-IQ1_S.colibri
Downloads
| file | for |
|---|---|
colibri-v2.1.0-linux-x86_64.tar.gz
| Linux x86-64 (AVX2), every engine with Vulkan built in |
colibri-v2.1.0-windows-x86_64.zip
| Windows x86-64 (AVX2), every engine with Vulkan and the AMD NPU lane; coli.cmd to start
|
colibri-v2.1.0-windows-x86_64-cuda.zip
| NVIDIA cards on Windows (compute 8.0 and newer): unpack it over the Windows archive |
colibri-v2.1.0-macos-arm64.tar.gz
| Apple Silicon; colibri, inkling and kimi_k3 with Metal |
SHA256SUMS.txt
| the checksums of the archives |
The one-step setup (START-HERE.bat on Windows, ./start-here.sh on Linux and macOS) picks the archive for your machine, or builds from source when a compiler is there. Every archive was unpacked and checked by CI before publishing: every engine present, coli dispatching to each one, the Vulkan engines finding their shaders, the dashboard and the chat UI loading.
What changes by default
- The KV caches are float16: colibri.c's MLA latent cache (GLM-5.2/5.3, Mistral-Large-4;
KV16, not with CUDA or Metal), qwen36's (Q36_KV=f32keeps float32) and qwen38's when serving (Q38_KV). Half the RAM of float32. - A short request between two turns parks the conversation on every engine serving one conversation (
COLI_PARK=0never parks).
Thank you
To the 35 people whose pull requests are in this release: @rudycelekli, @CoTi1938, @bobsummerwill, @Avicennasis, @appleguy, @Stamina9, @kreuzzelg, @simaotwx, @Altroo, @benmaster82, @namespaceMarcello, @JackKnifeAI, @leonwieser2009-oss, @Ontahm, @Varshith-Kali, @djairjr, @neerajdad123-byte, @dajiaohuang, @mfranzon, @huppiflupp, @seanfalling, @jameswitney, @KhalidAlnujaidi, @HyperionBurn, @TyrionV8, @kflirik, @bherald, @Anionex, @mfethe1, @ZacharyZcR, @ggeorgovassilis, @neoo69, @crichalchemist, @enitimeago and @pavolbauer. And to everyone who opened an issue with numbers from their own machine.
Everything in 2.1.0
New models
- #2493, #2500, #2503: Mistral-Large-4, the text model from every
published GGUF and from the FP8 release, on the CPU, the Vulkan chain and CUDA,
and its pictures (the Pixtral tower, from the GGUF's mmproj or our containers). - #2489, #2491: LFM3-VL's text model (from its GGUFs or the converted
checkpoint) and its pictures. - #2292, #2297, #2310, #2316: Flint, its safetensors and every
unsloth GGUF, on the CPU, Vulkan and CUDA; its sliding layers keep their K/V in
a ring. - #2293, #2324: Muse Spark Open from the unsloth GGUFs, CPU, Vulkan and
CUDA. - #2143, #2269: DeepSeek-V4.1-Flash-1017 as it is, and the published
DeepSeek V4.1 GGUFs with their DSpark head. - #2274: the published Kimi K3 GGUFs, on the CPU, the Vulkan chain and the
tier. - #2102: Qwen-Image gets a single-frame CPU VAE encoder.
GGUF on every engine
- #2130: GGUF models read natively, the CPU kernels interleaved by 16 rows.
- #2140, #2141: DeepSeek V4, Inkling, GLM-5.3 Flash, GLM-5.2, MiMo,
DeepSeek V4.1 and OLMoE read GGUFs too. - #2182, #2185, #2195, #2228, #2237, #2238: a GGUF's
dense matrices and routed experts on the Vulkan chain, its prompt on the
device's tiled and grouped GEMMs and on the matrix units; IQ1, IQ2, IQ3 and
K-quant block decoders. - #2252, #2254, #2255, #2491: a GGUF's block formats on CUDA,
Qwen3.6's and Qwen3.8's CUDA chains on a GGUF, the prompt GEMM on f16
mma.sync. - #2239, #2248: on an NVIDIA card a GGUF runs on Vulkan where CUDA does
not cover its work (GLM-5.2, DeepSeek V4, Kimi K3, Inkling). - #2503, #2515: colibri.c's GGUF experts and dense matrices on CUDA, and
F16 and BF16 matrices on the GPU as block formats (Qwen3-0.6B F16 on CUDA:
prompt 137 to 15,921 tok/s). - #2198, #2280: IQ2_S and IQ3_S rows in one gather; expert reads without
readahead (Kimi K3 decode +30 %).
CUDA
- #1992, #2089: every layer of Qwen3.6 and of Qwen3.8 as one chain on the
CUDA device (COLI_CUDA_CHAIN). - #2209, #2231, #2232, #2233: the routed experts in the chain's
frame, a prompt chunk's attention and GEMMs on the tensor cores, the experts
outside VRAM staged from the RAM cache. - #2276, #2277, #2278, #2279: a routed-expert tier on a CUDA
device for every engine (cu_tier), and the dense matrices on the card
(cu_dense.h) for DeepSeek V4, V4.1, Kimi K3, GLM-5.3 and MiMo. - #2257, #2332, #2377, #2395, #2416, #2417, #2423:
the card's residents follow the conversation, promoted from the host pool. - #2335: the Vulkan and CUDA chains serve several conversations at once, each
one's state on the device. - #2459, #2461: the decision engines (Laya, GLiNER2.5-Decide) and OLMoE,
every layer with its experts, on a CUDA card. - #2462, #2497, #2385, #2392, #2408, #2418, #2421,
#2453: programmatic dependent launch, add and norm in one pass, the MTP
head's draft on the device, one-pass prompt attention on sm_75.
Vulkan
- #2093, #2206, #2430, #2432, #2490: a layer's routing and
routed experts in the dense chain's frame; the host pool's experts on the CPU
beside the device's, measured against the device's reads and kept where they
win, inside the frame on events. - #2184, #2258, #2318: a host pool in system RAM the device reads, its
experts moving up to the device as a conversation routes them. - #2225, #2435, #2437, #2499, #2253: a prompt's GEMMs,
experts and attention on the matrix units at subgroups of 32, flash attention
with windows and sinks, vec4 reads (COLI_VK_CHAIN_GEMM_ROWSfor DeepSeek
V4's chain). - #2440, #2441, #2442, #2447, #2454, #2484: decode after
a long prompt, float16 KV mirrors, polling through a step, wider prompt tiles,
OLMoE's device KV cache (prompt +51 %). - #2046, #2328, #2404: the pipelines at the pinned subgroup size, the
cooperative matrix off by default on AMD's own driver.
Speculative decoding
- #2250, #2251, #2256: Qwen3.6's MTP head on Vulkan, CUDA and the
CPU; a verify's rows share the decode GEMV's weight loads and get its bits. - #2187, #2200, #2118: Qwen3.8's MTP head on the device.
- #2376, #2407: DSpark's verify depth from its confidence; the gate skips
drafts that cannot pay.
Long contexts, conversations and agents
- #1973: a conversation longer than the context goes on from a summary.
- #2113, #2114: a chat's next turn continues from what the engine holds,
its reasoning included. - #2326, #2327: the KV caches in float16 (GLM-5.3 at 131,072 tokens:
11.9 GB instead of 23.9). - #2517: Qwen3.8 Flash Next at a 256k context at the speed of 64k (prompt
15.6 to 149 tok/s, decode 9.6 to 45.7 on an RTX PRO 4000). - #2517, #2521: an agent's short request between two turns (a title, a
summary) parks the conversation instead of taking its state, on every engine
(COLI_PARK); Hermes on Qwen3.8 86 s to 4.9 s a turn, Qwen3.6-35B on the CPU
51.6 s to 3.3 s. - #2485, #2309: a served prompt stops on CANCEL while it is read, on every
engine; a dead engine starts again. - #2025: agents get the context they need.
The CPU
- #2042: SSSE3 integer-dot kernels for x86-64 CPUs without AVX2, bit-identical
to the scalar reference. - #2486, #2502, #2495, #2199: prompt reading on the CPU (OLMoE
2.5x, Qwen3.6 +15 %), the hot OpenMP team (decode up to +13 %), one place per
core, a hybrid CPU's team on its performance cores. - #2009, #2069, #2511: NEON paths (the int4 expert repack, the sparse
attention row) and faster DeepSeek V4 CPU decode kernels.
Interface
- #2505: a new chat UI (
coli ui): reasoning, pictures, web search, the
expert map, a live monitor, models, coding agents. - #2087, #2094, #2004, #2005, #2457: the web chat sends a past
turn's reasoning back and follows a streaming answer; Brazilian Portuguese;
coli chatreads documents (/file,--file). - #2144:
residency_sim.py --engine olmoereplays OLMoE traces with OLMoE's
own cache traversal.
Setup and platforms
- #1981, #1990: an engine on a processor without AVX2 says so; a clear
stop on an MSYS or Cygwin gcc. - #2026, #2095, #2099, #2100, #2197: setup applies the plan
off CUDA and takes--ctx, CUDA on Windows, models split across drives,
coli stop, GGUF import on Windows. - #2315, #2325, #2037, #2509: Windows heap and memory fixes, a
shard's readers overlapping. - #2396, #2397: a container's cgroup limit bounds the RAM.
Cluster
- #1962, #1963, #1964, #1967, #1969, #1970, #2120,
#2388: protocol v2, q8 activations on the wire, DeepSeek V4.1 expert
workers, bit-exact sums for any worker count.
Fixes and hardening
- #2522: a grammar whose alternates fan out into the same stacks no longer
holds up the engine (a fixed budget of walker steps a byte). - #2524:
/v1/systemoneanswers on GLM-5.2 and Mistral-Large-4 (the header
colibri.c reads). - #2523: a cold Qwen3.6 engine on the CUDA chain no longer hangs on a first
prompt of a few tokens. - #2457: the
/v1/systemoneerror body, and question ids up to 256
characters. - Over a hundred fixes across the API, setup, benchmarks, the MCP server, images,
audio, JSON schemas and LoRA adapters; 92 pull requests from rudycelekli alone. - #2527: the Windows builds with Vulkan (the host pool's imported pages without
posix_memalign), the dense-only RSS gates on Lavapipe measured without glibc's freed
blocks, and the README for 2.1.0.